Bulk File Operations
This section teaches you how to organize hundreds of files at once using the shell — no loops or Python required. You start with 300 disorganized files, each named in a cryptic format like fireball_fire_3_offensive_meteor.spell, and impose a clean structure on them.
Exercise
Three hundred files. No order. No organization. A real research dataset often looks exactly like this — files from a vendor, a scrape, an instrument dump. Your job before any analysis is to understand what you have and impose structure on it.
Task: Organize 300 files into a clean directory structure.
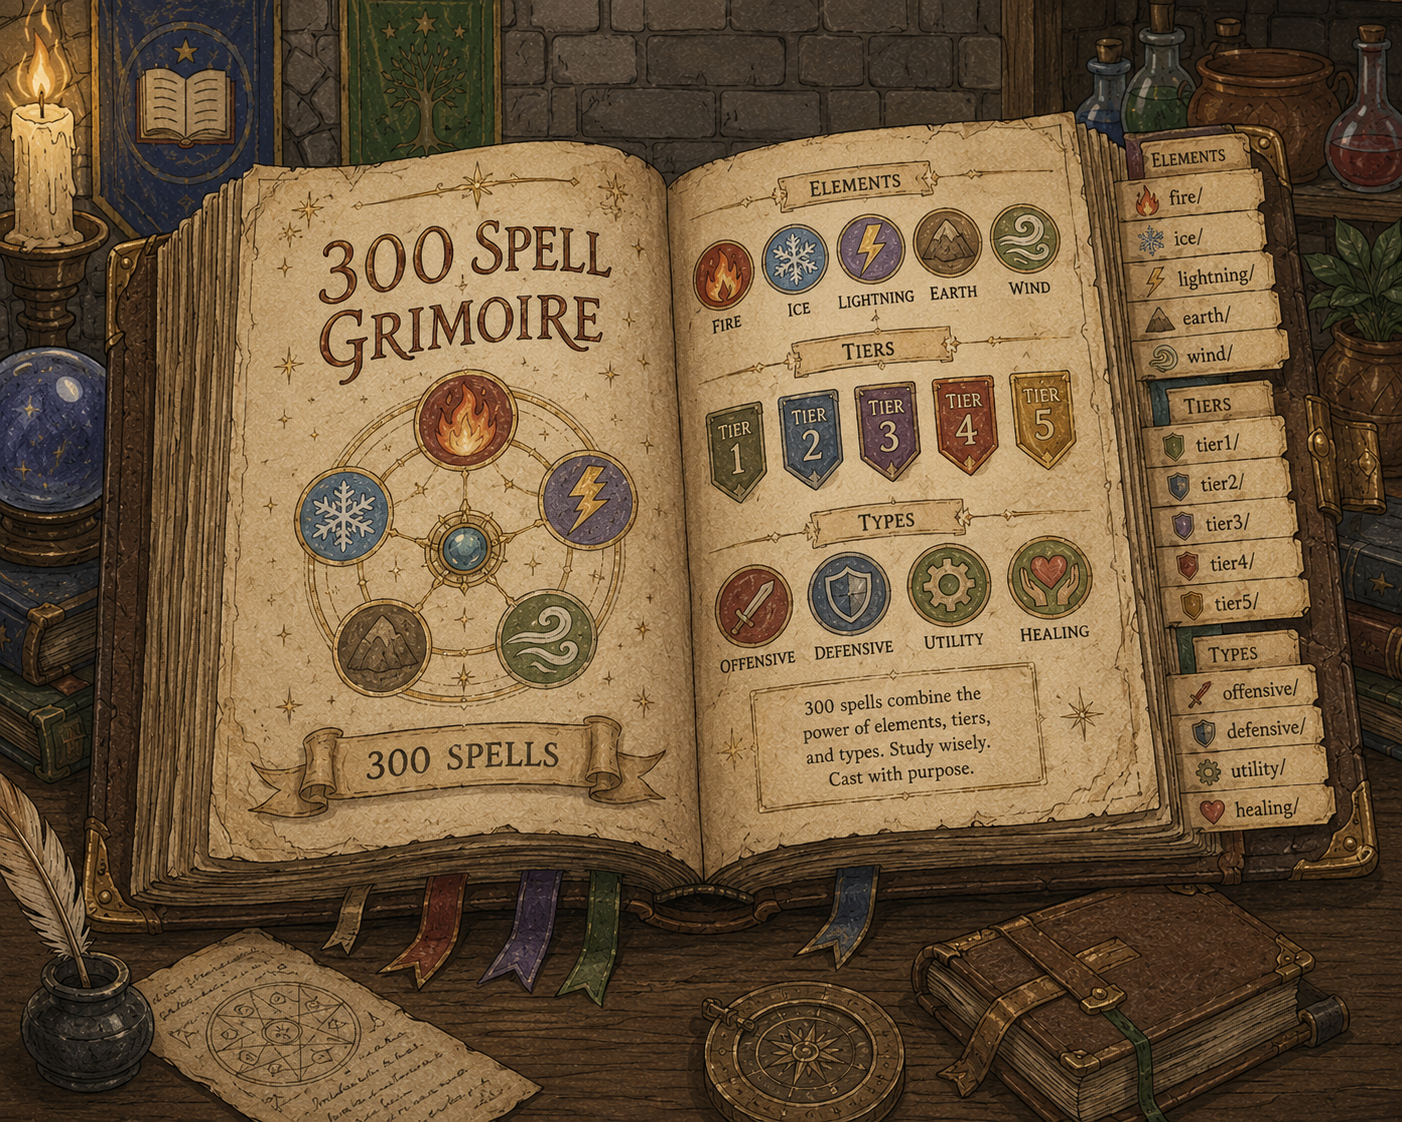
Every filename records three things about a spell — its element, its tier, and its type. Each of those is a different way you could group the 300 files, and choosing between them is part of the exercise.
Step 1 — Download and unzip
Download the dataset straight to your Desktop and unzip it (Git Bash on Windows, Terminal on macOS):
cd ~/Desktop
curl -L https://raw.githubusercontent.com/gsbdarc/gsb-research-computing-ai-skills/main/docs/assets/data/grimoire.zip -o grimoire.zip
unzip grimoire.zip
cd ~/Desktop— go to your Desktopcurl -L … -o grimoire.zip— download the archive and save it under that nameunzip grimoire.zip— unpack it into agrimoire/folder
Step 2 — Explore: look at what you have
Before touching anything, understand the data:
ls grimoire/ # see the files
The filename format is: name_ELEMENT_tier_type_mastery.spell
What elements do you see? What patterns are there? What would make a logical organization?
Ask questions with wildcards. The * wildcard matches any run of characters, so you can list just the files whose names contain a given piece. This is the most useful tool for getting a feel for a messy dataset:
ls grimoire/*_fire_*        # every file with _fire_ in its name
ls grimoire/*_5_*           # every tier-5 file
ls grimoire/*_healing_*     # every healing file
ls grimoire/*.spell         # every .spell file — all of them
* can go anywhere in the pattern, and you can use more than one — *_fire_*_healing_* matches fire healing files. Try a few combinations.
Count and preview with a pipe. The | character is a pipe: it takes the output of one command and feeds it as the input to the next. That lets you build a question out of small pieces. Two commands pair especially well with ls:
wc -lcounts lineshead -Nshows only the first N lines
ls grimoire/ | wc -l              # how many files in total
ls grimoire/ | head -20           # just the first 20 names
ls grimoire/*_fire_* | wc -l      # how many fire files
ls grimoire/*_5_* | wc -l         # how many tier-5 files
Read a pipeline left to right: list the fire files, then count how many lines that produces. You’ll reach for this pattern — ls a subset, pipe it to a counter or filter — constantly in real work.
🟢 Green sticky = I’m done and ready 🔴 Red sticky = I need help
Put a sticky note on your laptop lid so instructors can see where you are.
Step 3 — Plan: decide on a strategy
Class discussion — how would you organize these files? Raise your hand.
Options to consider (expand after discussion)
- Group by element (
fire/,ice/,lightning/,earth/,wind/) - Group by tier (
tier1/,tier2/, …tier5/) - Group by type (
offensive/,defensive/,utility/,healing/)
We will go with element — it is the most natural grouping for this dataset and maps cleanly to the filename structure.
Step 4 — Try by hand first
Before using the terminal, open Finder (Mac) or File Explorer (Windows). Navigate to Desktop/grimoire/. Create a fire/ folder and try moving 10 fire files into it by clicking and dragging.
Now imagine doing that for all 300 files across 5 elements. How long would it take? What happens when you get 10,000 files next year?
That is exactly what the terminal solves. This is the first skill you will use in real research — and you will reach for it again every time a new dataset arrives.
Step 5 — Execute: sort with wildcards
Now put the wildcard to work. *_fire_* matches every filename with _fire_ in it — all 60 fire files — so you can move them into a folder in a single command:
cd ~/Desktop/grimoire
mkdir -p fire ice lightning earth wind

mv *_fire_*.spell fire/
mv *_ice_*.spell ice/
mv *_lightning_*.spell lightning/
mv *_earth_*.spell earth/
mv *_wind_*.spell wind/
🟢 Green sticky = I’m done and ready 🔴 Red sticky = I need help
Put a sticky note on your laptop lid so instructors can see where you are.
Step 6 — Verify
Use the pipe from Step 2 to check your work — ls fire/ | wc -l lists the files in fire/ and counts them:
ls fire/ | wc -l      # count fire files
ls ice/ | wc -l       # count ice files
ls lightning/ | wc -l
ls earth/ | wc -l
ls wind/ | wc -l
All five counts should sum to 300.
You can also count everything at once:
ls */*.spell | wc -l # total files across all element folders
Task: Keeping Track
Create a file listing the names of all tier-3 files in the dataset.
The grep command searches for a pattern in input. Combined with ls and a pipe, you can filter filenames by any part of their name:
ls */*.spell | grep "_3_"
ls */*.spell | grep "_3_" > tier3_spells.txt
The first line lists all tier-3 files; the second saves that list to a file.
The > operator redirects output to a file instead of printing it to the screen. If the file already exists it is overwritten; use >> to append instead.
The cat command displays the contents of a file:
cat tier3_spells.txt               # view the file you just created
wc -l tier3_spells.txt             # how many tier-3 files there are
🟢 Green sticky = I’m done and ready 🔴 Red sticky = I need help
Put a sticky note on your laptop lid so instructors can see where you are.
Step 7 — Document: write a README
Always leave a note explaining what you did and why. Create a README.md in the grimoire folder:
nano ~/Desktop/grimoire/README.md
Write something like:
# Grimoire Archive

300 files sorted by element into subdirectories:
fire/, ice/, lightning/, earth/, wind/

Each filename follows the format:
  name_element_tier_type_mastery.spell

Organized: [today's date]
Save with Ctrl+O, exit with Ctrl+X.
This habit — documenting your organization decisions while they are fresh — is one of the highest-leverage things you can do for your research career. You will thank yourself in six months.
You will transfer your sorted files to the Yens in Transferring Files (scp). Keep this directory — you need it there.
Optional practice
Sort by type as well
Your files are now sorted into element folders. A researcher might also want to find all offensive files across every element at once.
Using cp (not mv) — so files stay in their element folders — organize the files by type into offensive/, defensive/, utility/, healing/ folders.
Think before you type: what wildcard would match all offensive files regardless of which element folder they are in?
Solution (expand after trying)
mkdir -p offensive defensive utility healing

cp */*_offensive_*.spell offensive/
cp */*_defensive_*.spell defensive/
cp */*_utility_*.spell utility/
cp */*_healing_*.spell healing/
*/* reaches into every immediate subdirectory at once — so */*_offensive_* matches offensive files inside fire/, ice/, lightning/, earth/, and wind/ all in one command. Using cp instead of mv means each file now lives in two places simultaneously: its element folder and its type folder.
Find the Rarest Combination
The filename format is name_element_tier_type_mastery.spell. Find the least common element + type combination across all 300 files.
The cut command splits each line on a delimiter and extracts specific fields. sort sorts lines alphabetically. uniq -c counts consecutive identical lines (so sort first). sort -n sorts numerically.
ls */*.spell | cut -d'_' -f2,4 | sort | uniq -c | sort -n
cut -d'_' -f2,4— split on_, keep fields 2 (element) and 4 (type)sort— group identical combos togetheruniq -c— count each groupsort -n— sort by count, smallest first
The rarest combinations appear at the top. What do you find?