Handling LLM Failure Modes
LLMs are remarkable tools — but, as we’ve all found out by now, they are also brittle. Even the best models get things wrong, often confidently, and often enough to matter. Before you trust an LLM’s output — especially at scale — you need a way to check it. The rest of this page discusses some of the failure modes to watch for, and how to build in checks to catch them before they reach your results.
Common Failure Modes
Let’s crowdsource your experiences with LLM failure modes. What are some different kinds you’ve experienced?
Some important categories (expand after discussion)
-
Hallucination — the model produces false output, such as an invented citation, number, or quotation.
Real-world case: in 2024, Stanford misinformation expert Jeff Hancock submitted expert testimony citing journal articles that ChatGPT had invented, and the court threw it out. (Lawyers have been sanctioned for the same thing.)
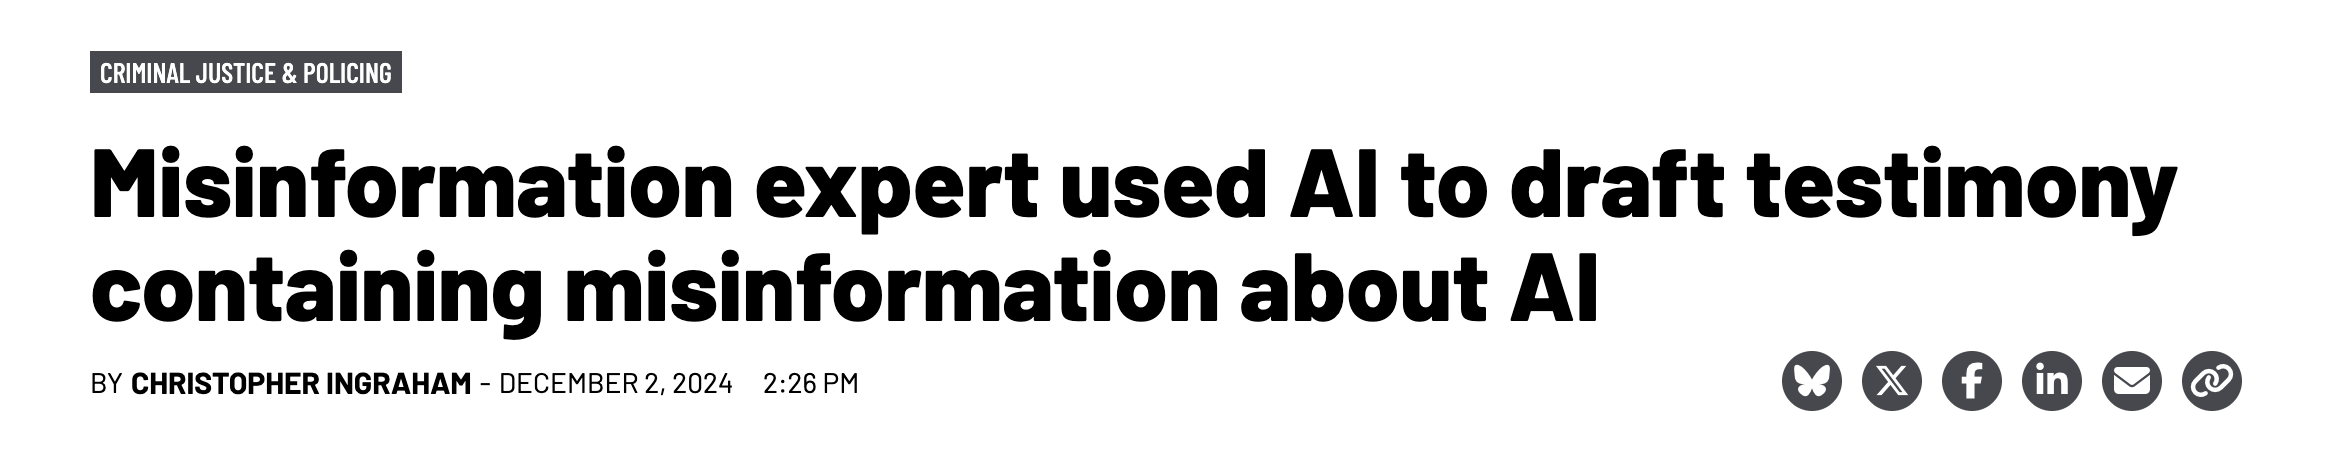
Source: Minnesota Reformer.
- Inconsistency — ask the same question twice and you may get two different answers (model outputs are probabilistic). Downstream tasks also often depend on the output having a consistent format or type, and that is not something you get for free.
-
A lack of guardrails — this matters most for agentic LLMs (like Claude Code), which don’t just answer but act on your system. An agent inherits the permissions you give it, so be deliberate about which ones you hand over: some actions can’t be taken back, and — as you saw with
rm— deleting or overwriting a file on the command line leaves nothing to recover.Real-world case: in early 2026 a user asked Claude to organize a desktop, and it deleted a folder holding roughly 15 years of family photos — thousands of files — with irreversible terminal commands.
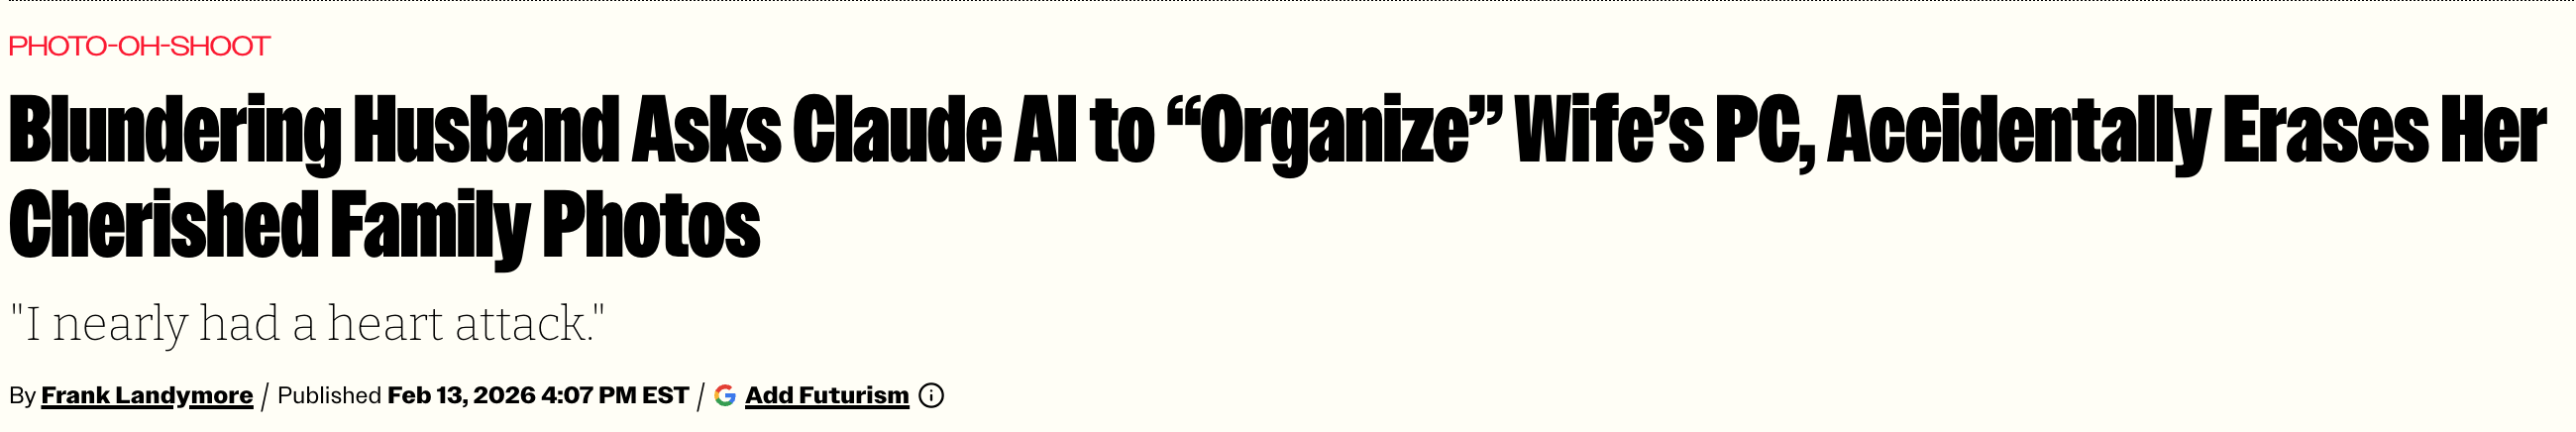
Source: Futurism.
-
An imperfect substitute for your own thinking — it can be easy to sit back and let your LLM drive, but there’s a risk of confusing rapid progress with true understanding.
AI researchers at Anthropic conducted a randomized experiment and found that developers who learned a new programming library with access to LLMs came out weaker at reading and debugging that code, and were no faster in executing tasks than the group without access to LLMs.
Source: Shen & Tamkin, “How AI Impacts Skill Formation” (2026).
Making LLM Pipelines More Robust
Because a model won’t necessarily flag its own mistakes, you have to check for correctness yourself. A few complementary “techniques”:
- Trade cost off against accuracy. Larger, more expensive models are generally more accurate, so if your budget allows, paying more per call is a simple step if accuracy is your primary concern. However, this is no substitute for the other approaches below.
- Add format and sanity checks. Cheap, automatic guards catch a surprising share of errors: validate structure and types with Pydantic, as you did on Day 1, and check ranges and formats against real-world logic — a date that isn’t a date, a negative probability, etc. Check the distribution of your outputs too: if you expect the data to be distributed a certain way and it isn’t, that may be an indication something has gone wrong.
- Compare across models. Run the same inputs through two different models and look at where they disagree. Models may fail in different ways, and disagreement is a cheap flag for “this item is uncertain,” pointing you to the cases worth reviewing.
- Spot-check a sample against ground truth. Have a notion of what the right answer is, then pull a random sample of outputs and check them against it by hand. Since your sample is random, if the outputs look reliable on the sample, it’s more likely they’re reasonable throughout.
- Ground high-stakes fields. For queries that really matter, have models quote the exact source text supporting each answer, so you — or a reviewer — can check it against the document.
Exercise: Putting This Into Practice
We saw above that comparing outputs between models is a basic robustness check. Now your job is to reprocess SEC filings, building on your existing scripts. This time, though, we want you to extract the outputs using multiple models and compare the outputs.
1. Call both models inside the loop. Start from the batch script you ran on Day 2, scripts/extract_form_3_batch.py, which already loops over filings from data/aws_links.csv. For each filing, make the same call twice — once per model — and save the answers side by side, in a dataframe or similar. Everything else stays as it was: the prompt, the schema, the loop.
Swapping in a second model is a one-line change. The same Anthropic client reaches every model the course key can use — only the
modelargument changes:import anthropic client = anthropic.Anthropic() # reads ANTHROPIC_API_KEY from the environment MODEL_A = "claude-haiku-4-5" # the model extract_form_3_batch.py uses MODEL_B = "claude-sonnet-5" # a slower, stronger second opinion # same call for each — only the model name changes answer_a = client.messages.parse(model=MODEL_A, max_tokens=4096, system=system_prompt, messages=messages, output_format=Form3Filing) answer_b = client.messages.parse(model=MODEL_B, max_tokens=4096, system=system_prompt, messages=messages, output_format=Form3Filing)And if you had a local LLM server running, you could of course compare against a local model too — that’s a second client pointed at the server’s own
base_url, as in GPUs & Local LLMs.
2. Decide what “agreement” means. Now that you have both sets of outputs in front of you, decide what counts as the same answer. For example, Smith, John and John Smith are the same person written two ways; whether your code should call that agreement is your call to make.
3. Count. Report two numbers: how many filings the two models agreed on, and how many they didn’t.
4. Inspect one disagreement. Pick a filing the two models disagreed on, open it, and work out which model was right — or whether both were wrong.
💡 Hint — reading the raw filing
A filing is just a text file at a URL, and data/aws_links.csv holds those URLs — the same ones your loop reads. Fetch the one you want and look at it directly:
import requests

filing_url = "..."            # the URL of the filing the models disagreed on
text = requests.get(filing_url).text

print(len(text), "characters")
print(text[:3000])            # the header, where the identifying fields sit
Alternatively, rather than reading the whole thing, search it for what each model reported:
for line in text.splitlines():
    if "<what the model reported>" in line.upper():
        print(line)
Bonus — Put a Guardrail on Your Agent
We said above that an agentic LLM inherits whatever permissions you give it, and that some of what it can do can’t be undone. Permission rules and hooks are how you draw that line.
A permission rule is a pattern the agent checks before acting — say, never delete a file, which is irreversible, as before. A hook is a script it runs at a fixed point in its own lifecycle, which can inspect the request and refuse it.
Rules cover most cases; hooks are for the ones a pattern can’t express — where the decision depends on something a pattern can’t see, like what’s inside the file or what state the repo is in.
Your task: set up a guardrail against a command you never want run without seeing it first. A rule is enough for this; hooks are there if you want to go further.
First, make something worth protecting. Run this at the repo root (~/yens-onboarding-2026):
touch important_file.txt
Second, ask Claude Code to protect it:
Add a permission rule to this project’s
.claude/settings.jsonthat stops you deleting files.
A rule that denies something takes precedence over anything that would allow it, so once it’s in place it holds regardless of what else is configured.
Third, try to trip it. Ask Claude Code to delete the file, then check with ls whether it’s still there.
Why this matters (expand after trying)
If the rule caught it, the file is still there and Claude will have told you it couldn’t run the command. That is the thing worth having, because telling a model in prose to be careful — in a system prompt, in a CLAUDE.md, in the request itself — doesn’t actually constrain it; it’s a request the model may or may not honour, and an injected instruction can talk it out of. Hooks and permissions are the only part of the arrangement that formally binds: the command doesn’t run, whatever the model thinks about it.
.claude/settings.jsonis committed with the project, so a rule you put there applies to everyone who works in the repo — not just you.~/.claude/settings.jsonis the same idea for every project on your account. If you want to explore further, the documentation covers permission rules and hooks.Neither mechanism is a Claude Code invention — Codex, Cursor and Gemini CLI all have hooks, with much the same lifecycle events, and each has its own way of restricting what the agent may run. The details differ; the idea transfers.
What You Learned
- You can name the main ways LLMs fail — hallucination, inconsistency, a lack of guardrails, and standing in for thinking you should be doing yourself
- You know that an agentic LLM inherits whatever permissions you give it, and that some of what it can do — deleting or overwriting a file — cannot be undone
- You have a set of robustness checks to reach for: paying for a better model, automatic format and sanity checks, comparing across models, spot-checking a sample against ground truth, and grounding the answers that matter most
- You ran the same filings through two models, counted where they agreed, and used a disagreement to find a case worth reading by hand
- You know that one endpoint serves many models, so trying a different one is a change of the
modelargument alone